-
Products & documentation Red Hat AI
A platform of products and services for the development and deployment of AI across the hybrid cloud.
Red Hat AI Enterprise
Build, develop, and deploy AI-powered applications across the hybrid cloud.
Red Hat AI Inference
Optimize model performance with an integrated stack for fast, consistent, and cost-effective inference at scale.
Red Hat Enterprise Linux AI
Develop, test, and run generative AI models to power enterprise applications.
Red Hat OpenShift AI
Build and deploy AI-enabled applications and models at scale across hybrid environments.
-
Learn Basics
-
AI partners
Why you should care about AI inference
Simply put, there’s no AI without inference. It’s at the core of generative AI.
The good news is, we know how successful it can be. The challenge is: how do we scale it?
Let’s break down how to scale AI inference with open source tools like vLLM and llm-d.
Why is inference so important?
Inference is the final step, when a model delivers the desired output. It’s a necessary function for AI to be successful.
That’s why the hardware and software that support inference can make or break your AI strategy.
The architecture with the most options for scaling is built on open source technology.

What’s holding you back from scaling?
We know that AI works—the challenge is scaling it across your enterprise.
When you scale, models require more data and more memory. That’s when hardware and accelerators struggle to keep up.
A third-party provider seems like the easiest solution. But token costs add up quickly, and sometimes exceed the AI application itself.
40%
By 2030, inference will be the dominant workload in AI data centers, expected to consume up to 40% of total data center demand.1
So, how do you make inference better?
When you optimize inference on open source architecture, AI models can run faster and smarter.
Optimization strategies include:
- Compressing models with quantization.
- Processing GPUs more efficiently.
- Speculative decoding.
- Distributed inference.
- Offloading memory and orchestration tasks to CPUs
Optimizations like these help AI inference stay cost effective, so it can scale with your teams as you go.
19%
Cost savings at scale when using speculative decoding techniques.2

2x
More computational throughput using compressed models, without sacrificing accuracy.3
90%
Total end-to-end latency accounted for by CPUs.4
How does vLLM optimize inference?
Optimizing models is only half the battle. You also need a high-performing inference engine. That’s where vLLM can help.
Traditional LLM memory management systems don’t organize memory in the most efficient way, which makes LLMs move slowly. vLLM uses PagedAttention, a memory management technique that identifies repetitive key values to reduce extra work for the LLM.
This allows vLLM to make better use of GPU memory and speed up generative AI inference. It maximizes throughput (tokens processed per second) to serve many users at once.
Using accelerators more efficiently means models can do more math in less time, so teams can serve more users and agents faster.
75%
Memory requirements reduced, decreasing required GPUs.5
4x
Tokens-per-second processed compared to the majority of inference providers.6
24x
Higher throughput performance with vLLM compared to competitors.7
Why is vLLM so popular?
vLLM has helped address the core issues around efficient GPU utilization, unlocking lower cost per token, stable latency at scale, and doing it with an open, portable deployment approach.
With Day 0 support for all major models and accelerators, its accessibility is attractive to both industries and academia. That’s why the vLLM community is active and vibrant.
Contributions come from Hugging Face, UC Berkeley, NVIDIA, Red Hat, and many more. The community consistently challenges and improves the software in the open source project.
10K+
vLLM GitHub commits*—an increase of over 200%—in 2026.
The vLLM community today
500K+
GPUs deployed 24/78
200+
Different accelerator types9
500+
Supported model architectures9
3.1K+
Where does distributed inference fit in?
Distributed inference allows AI models to divide the labor of inference across a group of interconnected devices.
When a model can fulfill different requests—all at the same time—it significantly reduces the necessary hardware and increases inference efficiency.
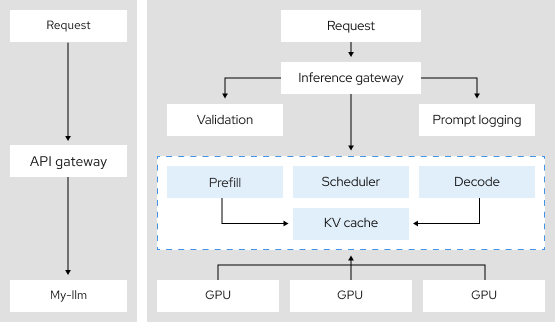
Distributed inference uses techniques like tensor parallelism, intelligent inference scheduling, and disaggregation. When layered with vLLM, inference becomes a very efficient, multitasking machine.
This helps inference stay observable, scalable, and consistent.
99%
Lower time to first token (TTFT) under equivalent load.10

Is there an open source community for that?
Yes, it’s called llm-d.
llm-d is an open source framework that gives developers a blueprint for building distributed inference at scale.
Its modular architecture supports the complex resource demands of sophisticated LLMs and replaces manual, fragmented processes with integrated well-lit paths, speeding up the time from pilot to production.
llm-d brings inference to Kubernetes, providing a standardized tool-kit that helps apply distributed inference to your unique enterprise use cases.
2x
Users sustained on the same hardware using llm-d-optimized clusters.11
More AI resources
Red Hat AI Inference
Move your LLMs from code to production faster.
Built on vLLM, our enterprise-grade inference engine enables faster inference without sacrificing performance.
Scale across the hybrid cloud with your preferred and optimized gen AI model, on any AI accelerator, in any cloud environment.

Cited sources
[1] “The future of AI workloads.” McKinsey & Company, 24 Feb, 2026.
[2] Umesh, Harshith. “Performance improvements with speculative decoding in vLLM for gpt-oss.” Red Hat Developer Blog, 16 April, 2026.
[3] Kurtić, Eldar, et al. “2:4 Sparse Llama: Smaller models for efficient GPU inference.” Red Hat Developer Blog, 28 Feb, 2025.
[4] Bowerman, Sawyer. Ableidinger, Grace. “The CPU is back: Rethinking the CPU-GPU split for LLM inference.” Red Hat Blog, 6 Aug, 2026.
[5] “What is LLM Compressor?” vLLM documents.
[6] “vLLM Tops the Artificial Analysis Leaderboard.” vLLM Blog, 11 May, 2026.
[7] Kwon, Woosuk, et al. “vLLM: Easy, Fast, and Cheap LLM Serving with PagedAttention.” vLLM Blog, 20 June 2023.
[8] Goin, Michael. “[vLLM Office Hours #38] vLLM 2025 Retrospective & 2026 Roadmap - December 18, 2025.” YouTube, Dec. 8, 2025.
[9] Kwon, Woosuk. “Today, vLLM supports 500+ model architectures, runs on 200+ accelerator types, and powers inference at global scale.” X, Jan. 26, 2026.
[10] Singh, Naina. “The same 16 GPUs, twice the users: Inference-aware routing for LLM clusters” Red Hat Blog, 27 May, 2026.
[11] Singh, Naina. “The same 16 GPUs, twice the users: Inference-aware routing for LLM clusters” Red Hat Blog, 27 May, 2026.
